DiscoverAI, a free five-minute check
Do you need your own AI model?
Usually not. Most firms that want to use AI on their own data need a clean pipeline in front of a model that already exists, not a model of their own. Answer ten questions about your data, your setup and what AI is failing at today, and we will email you a short, honest read on where you sit on the decision ladder, how exposed the personal information (PII) in your data is, and the three things to do first.
Your name and email never reach the model, and the read is a high-level starting point, not an assessment. Read how that works.
We practise what the article preaches
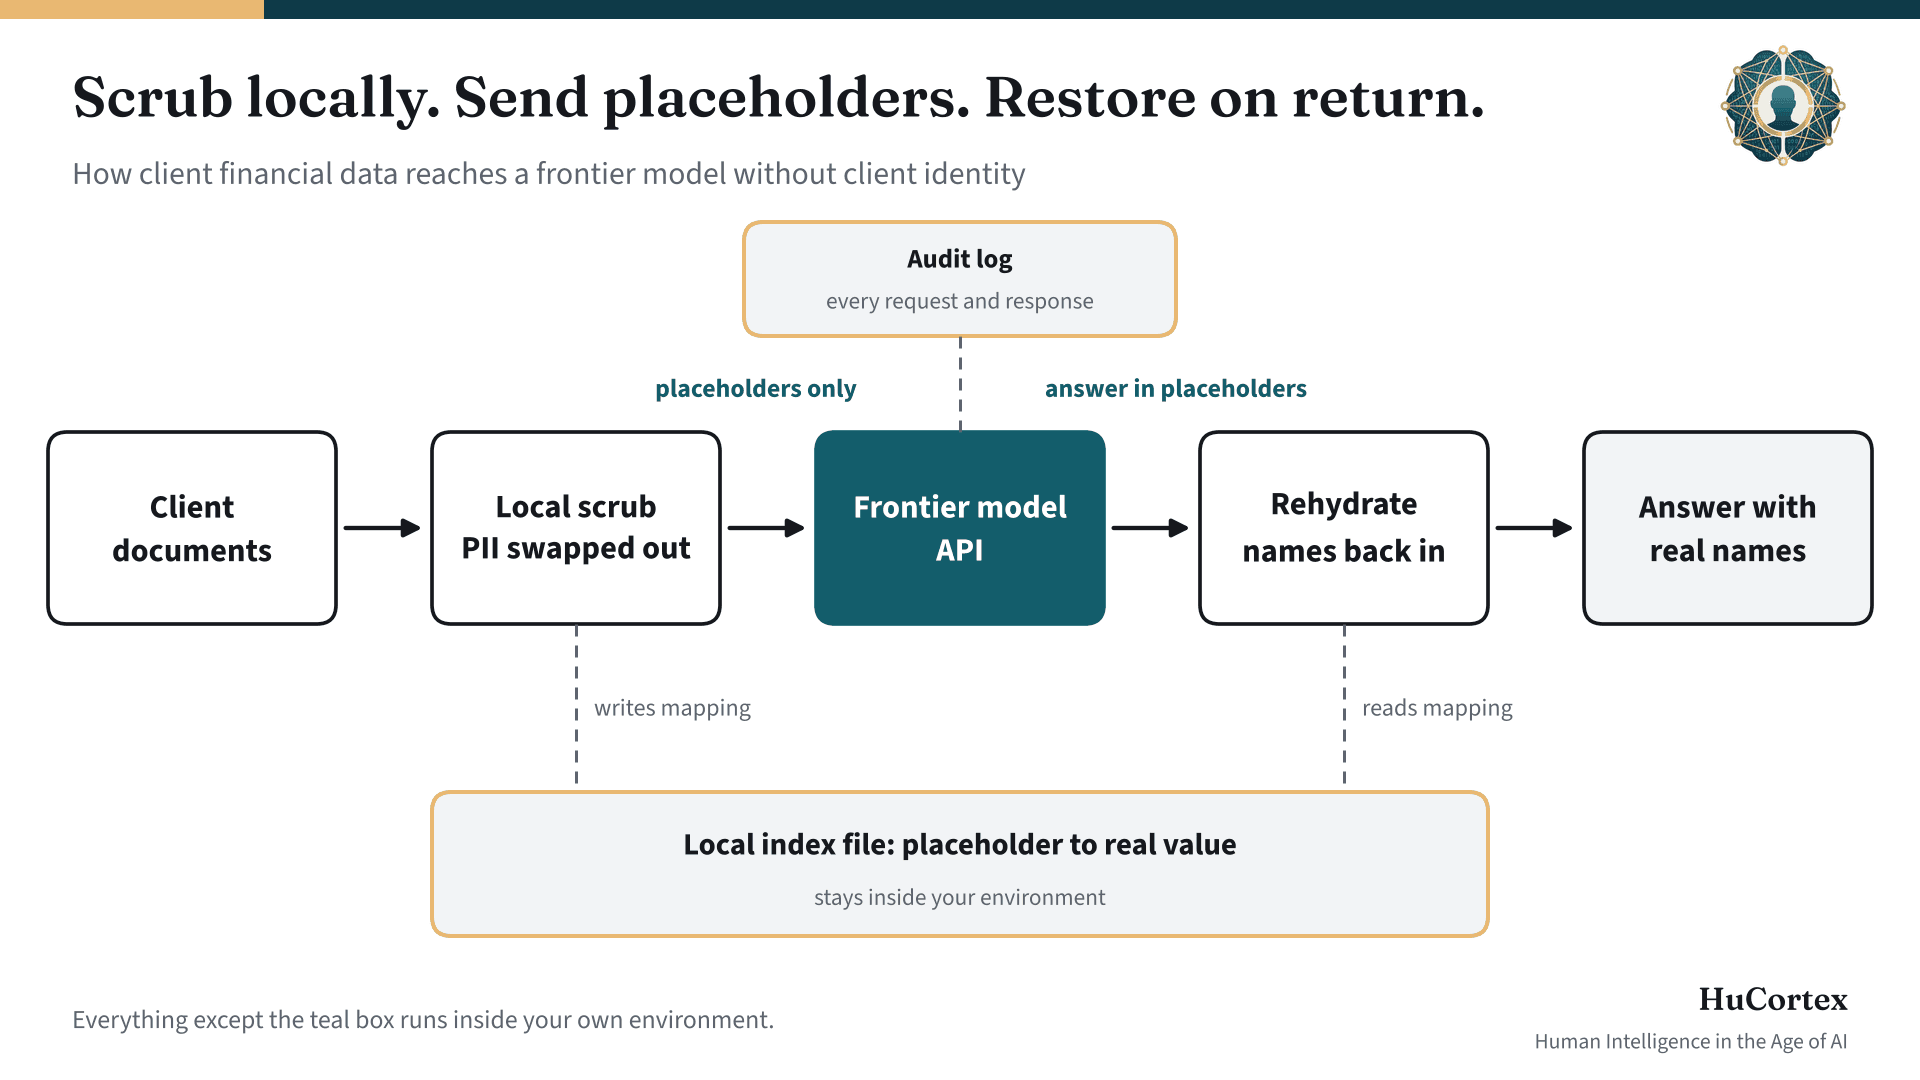
Your name and email never reach the model. Every answer below is a fixed choice, so what the model sees is a handful of labels like ACCOUNTING_FIRM and SIN_OR_GOVERNMENT_ID. It writes the read for you, our team sends it, and nothing about you is stored on this site. That is the scrub-and-send pipeline from the article, running on the form you are about to fill in.
A note on scope
Ten fixed-choice questions cannot capture how your firm actually works. The read you receive is a high-level starting point, drawn from your answers and the article's framework. It will miss things that only a conversation and a look at your systems would surface, so treat it as the first page of an assessment, not the assessment. The detailed version is a scoped engagement with HuCortex, available if and when it is useful to you.
What the read covers
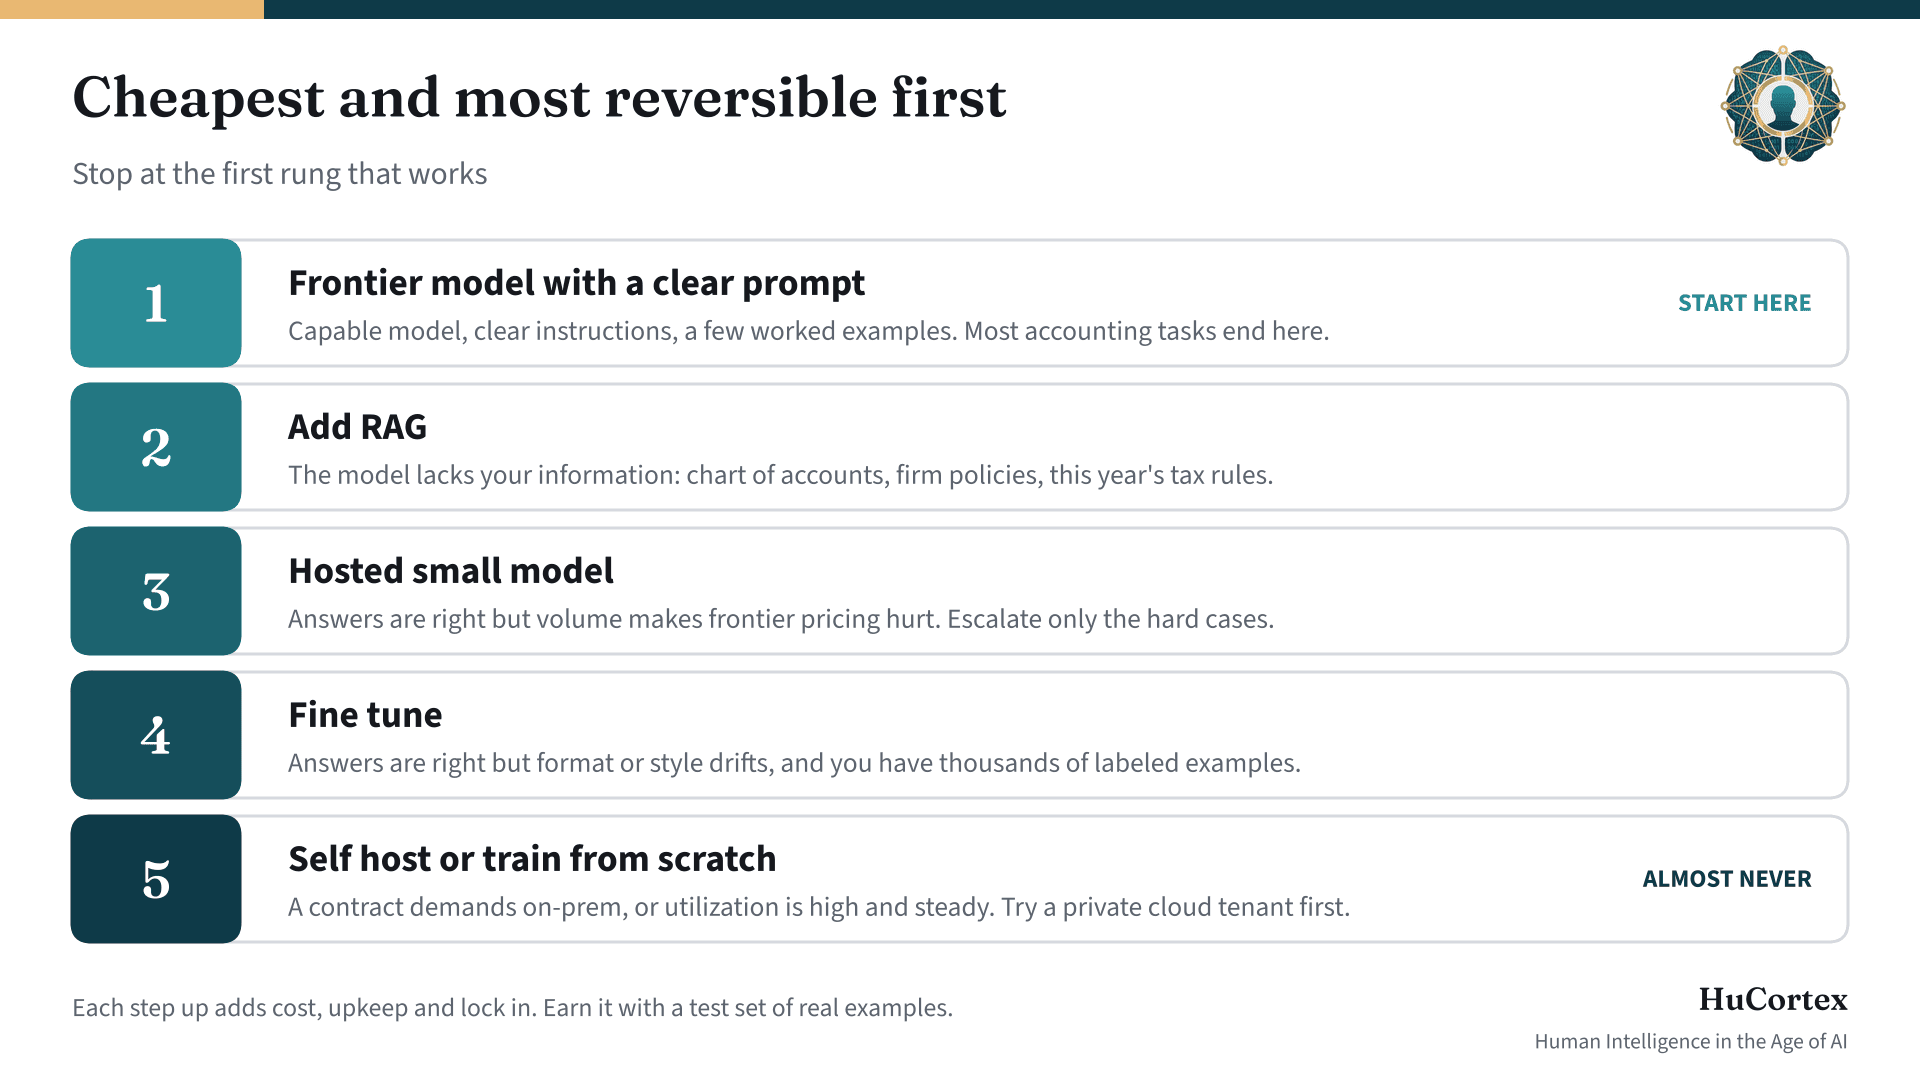
The article makes three arguments: the model was never the problem, a scrub-and-send pipeline is what keeps real identities out of it, and the expensive options (fine tuning, self hosting, training) should be earned by a failed test, not assumed. Your read applies each one to your answers.
Read the article: How to use frontier AI on your data without exposing PII
- Ladder step
- Where your situation lands on the five-step ladder, from a frontier model with a clear prompt to self hosting, and why the lower step is usually enough.
- Exposure
- How exposed the PII in your data is today, given what is in it and how it reaches a model, with the one change that moves it most.
- Privacy
- Which rows of the Canadian and UK privacy table apply to you: PIPEDA, Quebec Law 25, UK GDPR, cross-border notice and breach records.
- Three steps
- The three things to do first, in order, written for your firm and your role.
Common questions
Does the model see my name, email or firm?
No. Those go to our team through Formspree and to the email you enter. The model receives only the fixed labels behind your answers, such as ACCOUNTING_FIRM, SIN_OR_GOVERNMENT_ID and NO_AUDIT_LOG. It is the same scrub-and-send approach the article describes.
Why email instead of showing the result on screen?
Two reasons. A person at HuCortex sees every read before anything else happens, which keeps us honest about what a model wrote. And an email is something you can forward to a partner or a colleague without screenshotting a web page.
How complete is the read?
It is deliberately high level. Ten fixed-choice questions cover the article's framework, not your firm's systems, contracts or the people in your records, so the read will miss things a conversation would catch. Treat it as a starting point. A detailed assessment is a scoped engagement with HuCortex, and whether to take that step is entirely your call.
Is this legal advice?
No. It is a practitioner's read based on the privacy requirements we checked in October 2026 and on your answers. Run anything you put in a notice or a contract past a privacy lawyer.
What happens to my answers?
They are sent once to the model to write your read, once to our inbox with the read attached, and once to you by email. Nothing is stored on this site and there is no database behind it.
When a detailed assessment makes sense
The read tells you where to start. A detailed assessment looks at the actual systems, contracts and the data you hold, measures the scrub miss rate on real documents, and ends with a pipeline you can explain in two minutes to a regulator, an auditor or anyone whose record is in the system. HuCortex does this as a fixed-scope engagement, usually a few weeks. If that is useful, book a time; if not, the read stands on its own.
Book a time